GENERATION-AWARE KV COMPRESSION
NanoKVHigh-Ratio KV Cache Compression for Autoregressive Video Generation
Generation-aware compression preserves the downstream effect of historical KV, with an optional Fast mode for mixed-dimensional attention.
1 Zhejiang University 2 NVIDIA
* Corresponding author
26.09×
Effective KV compression
HY-WorldPlay · NanoKV
35.9%
Lower peak GPU memory
HY-WorldPlay · teaser configuration
<10%
End-to-end latency overhead
NanoKV vs. Original · all three backbones
01 / VISUAL RESULTS
Video comparisons
Original and compressed generations, side by side.
HY-WorldPlay
Alpine panorama
Prompt
In the majestic expanse of a clear blue sky, a solitary mountain, blanketed in pristine white snow, stands as a testament to the grandeur of nature. The mountain, the central focus of this image, is captured from a low angle, emphasizing its imposing height and the vastness of the sky that surrounds it. The camera pans upwards, following the mountain's contours, culminating in a high shot that showcases the peak. The sun casts a warm glow on the snow-covered surface, illuminating the mountain's texture and creating a sense of tranquility. The image is a harmonious blend of the mountain's raw beauty and the serene atmosphere, capturing a moment of quiet solitude in nature's embrace.
Snow-covered cottage
Prompt
In this image, a cozy two-story house with a green facade and white trim is nestled amidst a snowy landscape. The front door is invitingly decorated with a wreath, and the staircase leading to it is covered in a thick blanket of snow. Snow-covered shrubs and trees frame the house, creating a serene winter scene. The camera should start with a wide shot of the house, then slowly zoom in on the front door, pausing on the wreath to emphasize the festive atmosphere. As the camera continues its zoom, it should pan up to the top of the house, highlighting the snow-covered roof and chimney. The lighting should be soft and warm, enhancing the comforting ambiance of the scene. The background should be a gentle blur, with the focus remaining on the house and its details.
LingBot-World 2.0
Tropical coast
Prompt
Create a cinematic scene of a tranquil beach under a sunny sky. The main subject is a person, standing on the left side of the sandy beach, facing towards the right. They are dressed in casual beach attire and appear to be contemplating the vast ocean. The camera should start with a wide shot, panning from the person to the horizon, capturing the vastness of the ocean and the sky. As the camera moves closer, it should focus on the person's face, showing their relaxed expression. The sunlight should be bright but not harsh, casting soft shadows and highlighting the person's silhouette against the light sand. The palm trees in the background should sway gently, adding a sense of movement to the scene. The overall atmosphere should be serene and peaceful, conveying a sense of relaxation and tranquility.
Lakeside pagoda
Prompt
The image presents a tranquil scene of a pagoda perched atop a mountain in Japan. The main subject is a red and black pagoda, standing tall and majestic against the backdrop of a clear blue sky. The pagoda is nestled amidst lush green trees and bathed in the soft glow of the sun, which casts a warm light on the scene. The camera movement should be subtle, capturing the pagoda from a low angle, giving a sense of its towering presence. The background should be a beautiful, panoramic view of the Japanese landscape, including the mountain's peak and the city in the distance, all under a clear blue sky. The overall tone of the image should be serene and peaceful, evoking the spiritual and cultural significance of the pagoda in Japan.
Matrix-Game 3.5
Karst lake
Camera control
Camera pans right, then left.
Sunlit cafe
Camera control
Camera pans left, then right.
02 / THE METHOD
Generation-aware compression.
Different objectives for Keys and Values.
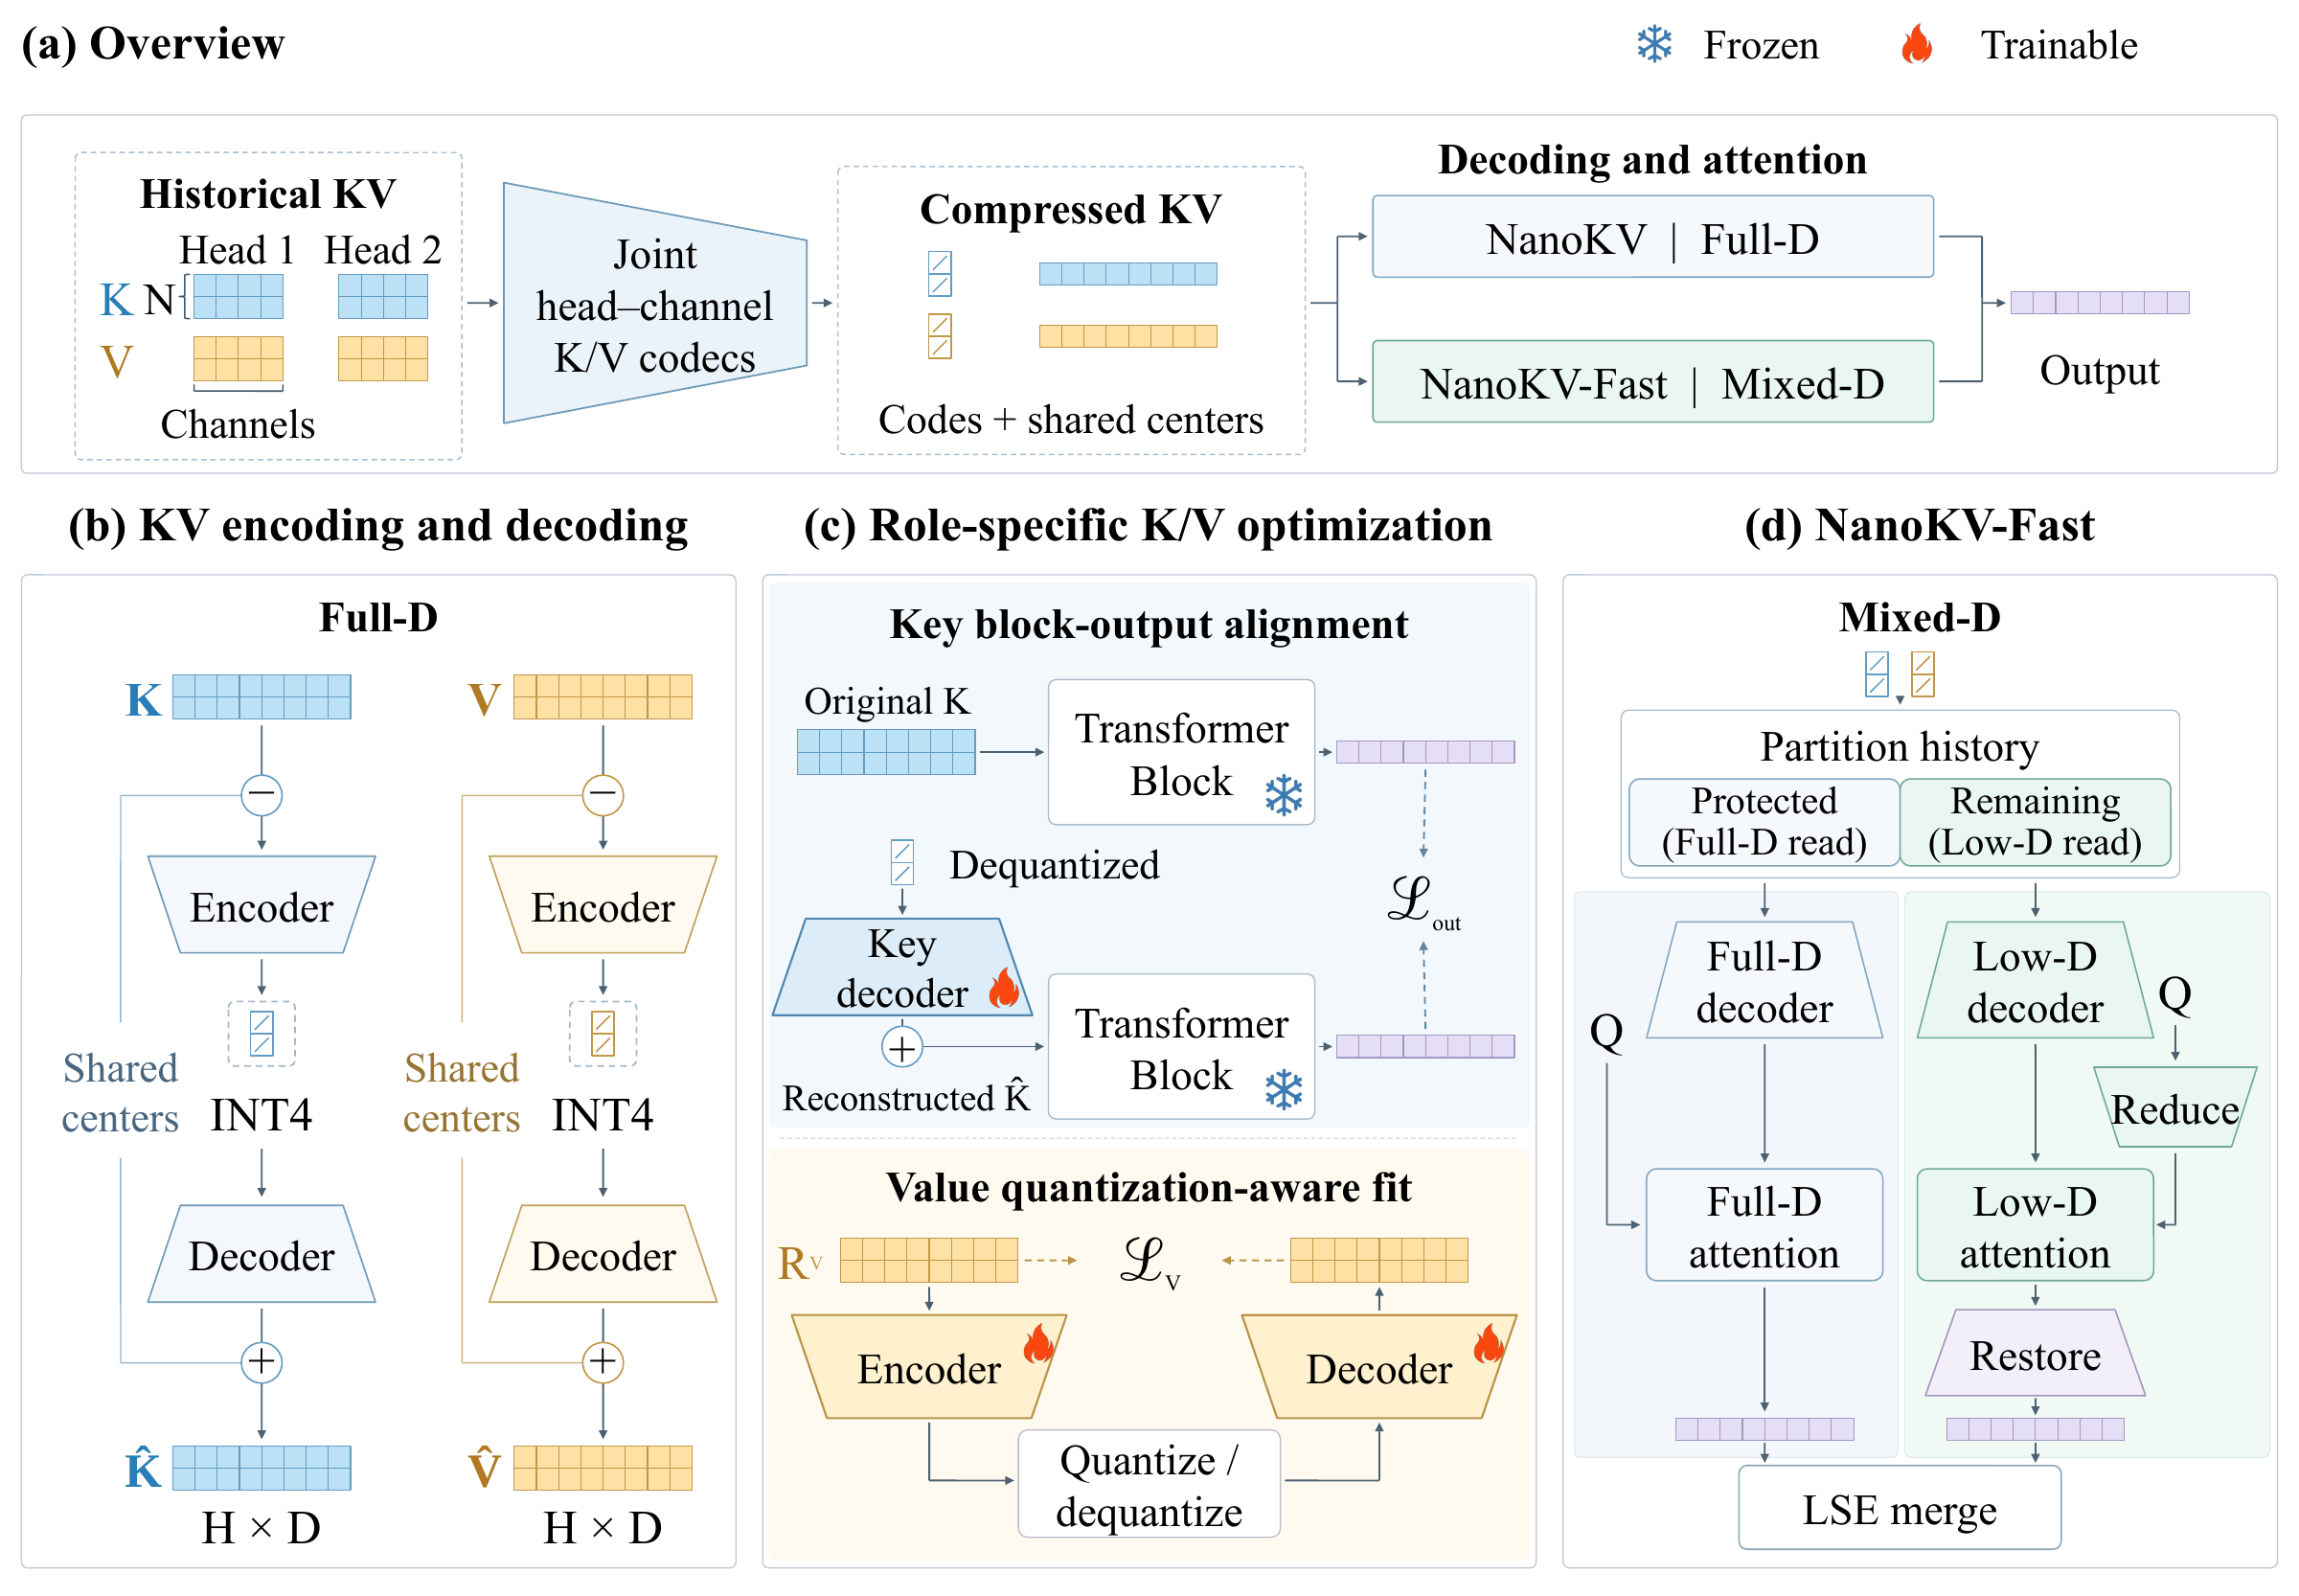
High-ratio compression is more than reconstructing KV features. NanoKV preserves the downstream effect of compressed history on generation.
Read the abstract
Autoregressive video models rely on historical key–value (KV) caches to preserve scene consistency over extended rollouts, making KV storage and repeated attention over history a growing memory and computational bottleneck. Aggressive compression can degrade generation quality, while reconstructing full-dimensional KV leaves attention computation largely unchanged. We introduce NanoKV, a frozen-backbone framework for generation-aware high-ratio KV compression. NanoKV exploits redundancy across tokens and attention heads by storing shared content in cluster centers and encoding joint head–channel residuals into low-bit coefficients. Crucially, NanoKV uses different fitting objectives for Keys and Values according to their distinct roles in attention: Key decoders are optimized to preserve downstream block outputs, whereas Value encoders and decoders are fitted for faithful reconstruction through the deployed quantization path. Building on the same compressed representation, the optional NanoKV-Fast variant reuses the stored coefficients for mixed-dimensional attention, reducing computation without modifying the video backbone. Across three autoregressive video backbones, NanoKV consistently improves the quality–storage trade-off. On HY-WorldPlay, NanoKV achieves 26.09× effective KV compression—nearly twice that of KVTC—while improving PSNR by 1.0 dB. NanoKV-Fast retains 20.53× effective compression and achieves an approximately 1.15× end-to-end speedup over KVTC.
03 / MEASURED RESULTS
Quality, storage, and efficiency
400 videos per configuration. Matched inputs and generation settings within each backbone. Nominal 32× coefficient compression.
Total KV storage GiB · lower is better
Effective compression includes method-specific storage overhead.
| Method | PSNR ↑dB | KV compression ↑effective | E2E speedup ↑vs. Original |
|---|
37.93% less historical-attention computation
NanoKV-Fast computes mixed-dimensional attention from the same compressed KV representation.
PSNR relative to Original · Runtime measured on a single NVIDIA A100.
04 / REPRODUCE & BUILD
Start with your backbone.
Data collection, codec fitting, optional Fast reader fitting, and inference—all with a frozen generator.
Environment setup ↗Download NanoKV codecs and Fast readers ↗
Citation
@misc{lu2026nanokv,
  title={NanoKV: High-Ratio KV Cache Compression for Autoregressive Video Generation},
  author={Jiacheng Lu and Haoyi Zhu and Sipei Yi and Enze Xie and Cheng Zhuo and Yu Li},
  year={2026},
  url={https://github.com/jiacheng-lu03/NanoKV}
}